Continuous Time-Varying Emotion Control Zero-Shot Text-To-Speech With Emotion Orthogonal LoRA
This page presents demo samples for EO-LoRA, a method for continuous and time-varying emotion control in zero-shot text-to-speech. The model injects Valence, Arousal, and Dominance (VAD) signals through three aligned low-rank branches, and Flow-DGPO further improves controllability while preserving intelligibility and speaker similarity.
Overview
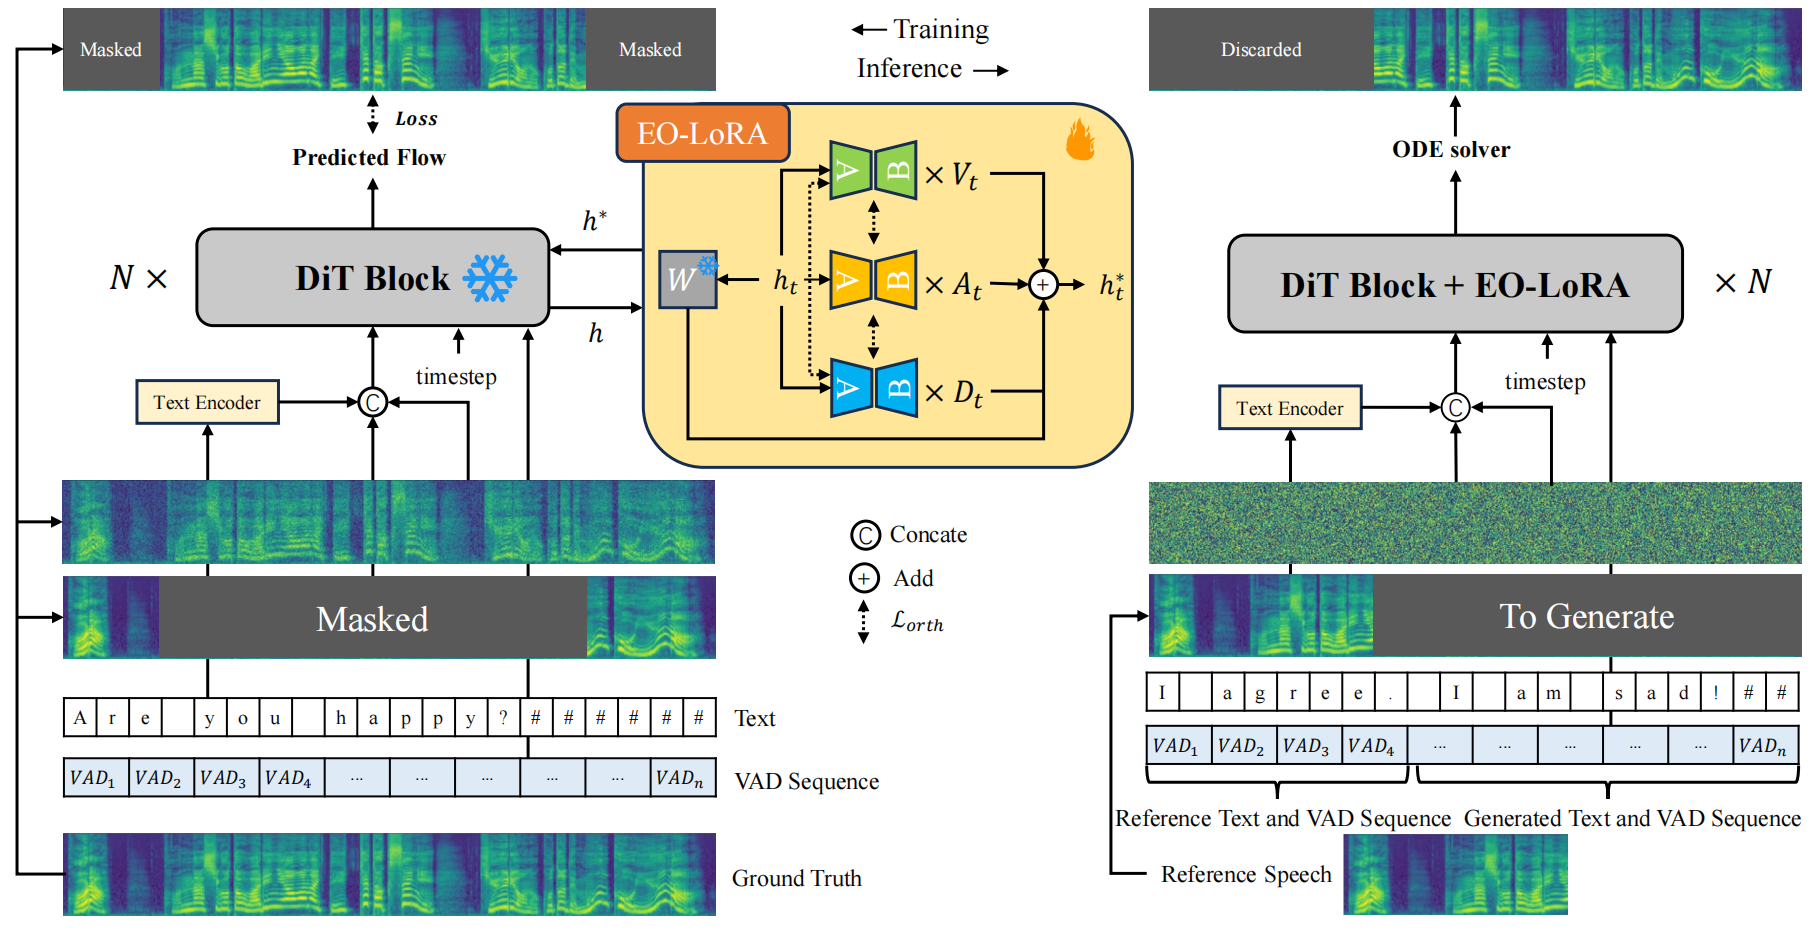
EO-LoRA performs continuous emotion control with VAD-aligned LoRA branches and supports time-varying emotional trajectories within a single utterance. Flow-DGPO is used as a preference-based alignment stage to further improve controllability.
Model overview
Samples
The layout below follows a horizontal comparison style. Each setting contains two rows for male and female examples.
Time-varying emotion control
Our model can generate a speech that closely mimics the time-varying emotional states found in the audio prompt. In these demo samples, the audio prompt is created by concatenating two audio samples from RAVDESS data set. The text prompt is “dogs are sitting by the door dogs are sitting by the door” for all generated speech samples. Each setting includes, F5-TTS (finetuned), EO-LoRA, and EO-LoRA + Flow-DGPO.
| Transition | Gender | Audio prompt | F5-TTS (finetuned) | EO-LoRA | EO-LoRA + Flow-DGPO |
|---|---|---|---|---|---|
| Angry → Calm | Male | ||||
| Female | |||||
| Sad → Surprised | Male | ||||
| Female | |||||
| Happy → Disgusted | Male | ||||
| Female | |||||
| Calm → Fearful | Male | ||||
| Female |
JVNV samples
Our model can be applied to speech-to-speech translation, transferring not only the voice characteristic but also the precise nuance of the source audio. The source audios were sampled from the JNVN dataset, which is a Japanese staged emotional speech corpus.
| Emotion | Gender | Audio prompt(Japanese) | F5-TTS (finetuned) | EO-LoRA | EO-LoRA + Flow-DGPO |
|---|---|---|---|---|---|
| Happy | Male | ||||
| Female | |||||
| Sad | Male | ||||
| Female | |||||
| Angry | Male | ||||
| Female | |||||
| Surprised | Male | ||||
| Female | |||||
| Disgusted | Male | ||||
| Female | |||||
| Fearful | Male | ||||
| Female |